JAPAN // TOKYO
48 GPUs
Robotics AI Cluster Build
Deployed custom liquid-cooled PARICH GI4205L servers integrated with 100G RoCE networking for real-time model inference and physics simulation.
Direct liquid-cooled GPU servers, modular container pods, and turnkey site integration. Built for extreme thermal efficiency and rapid cluster scaling.
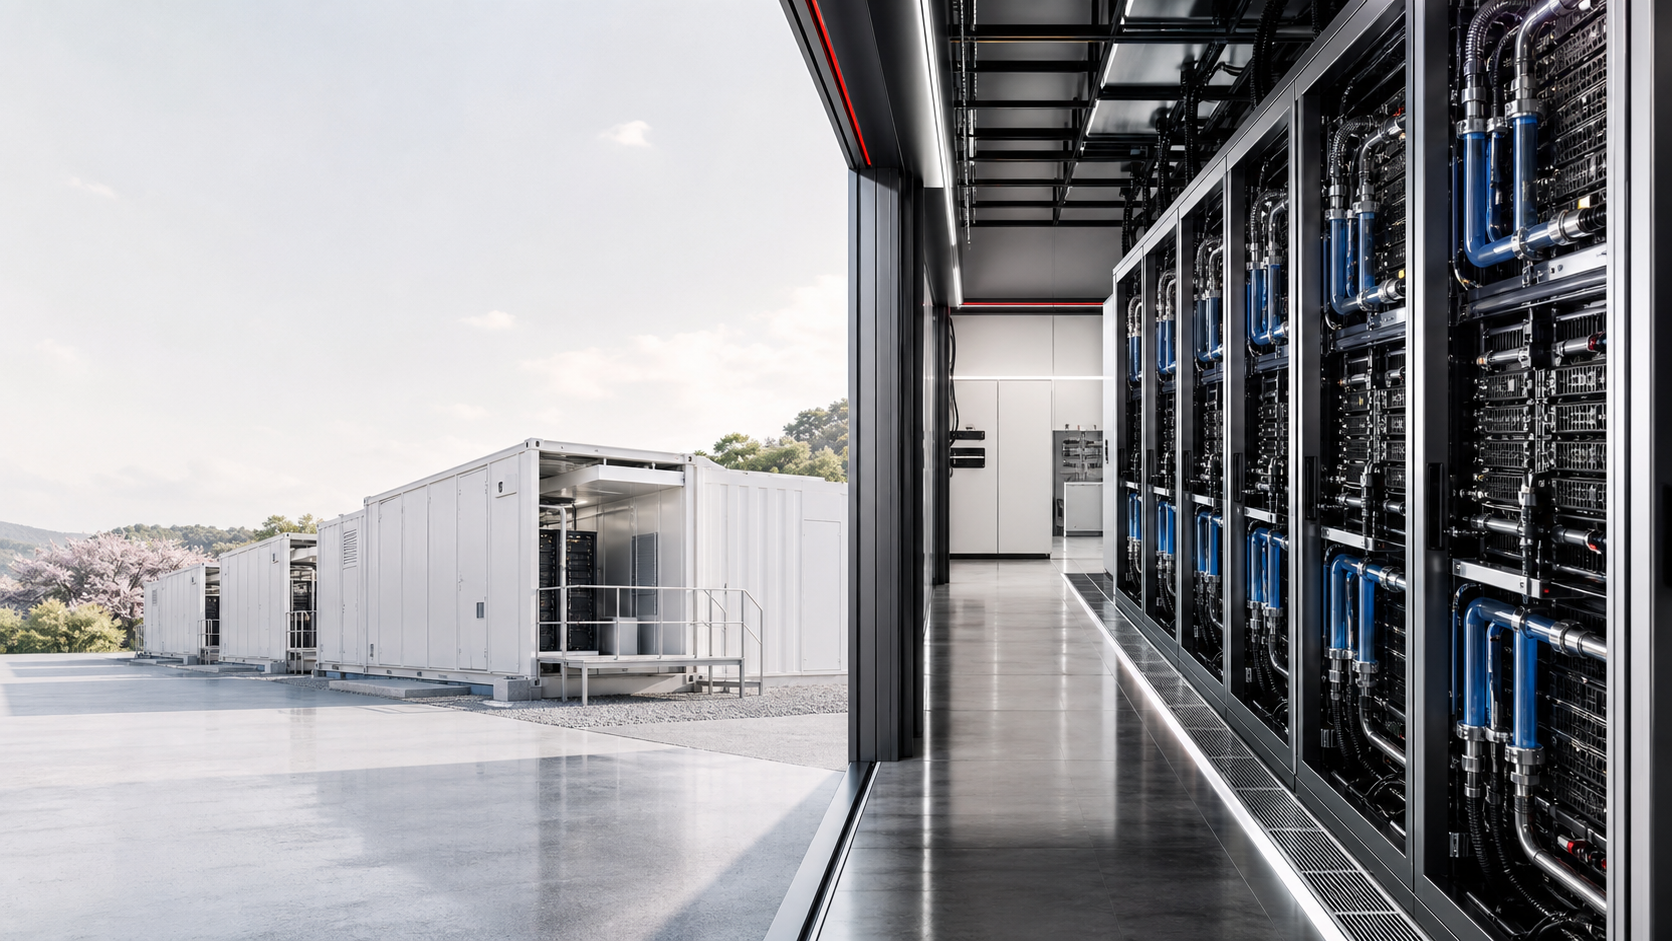
PARICH eliminates multi-vendor friction by unifying server hardware, thermal loops, containerized facilities, and operations into a single deployable stack.
Direct liquid & air-cooled 4U GPU servers designed for TDPs up to 350W+ per CPU.
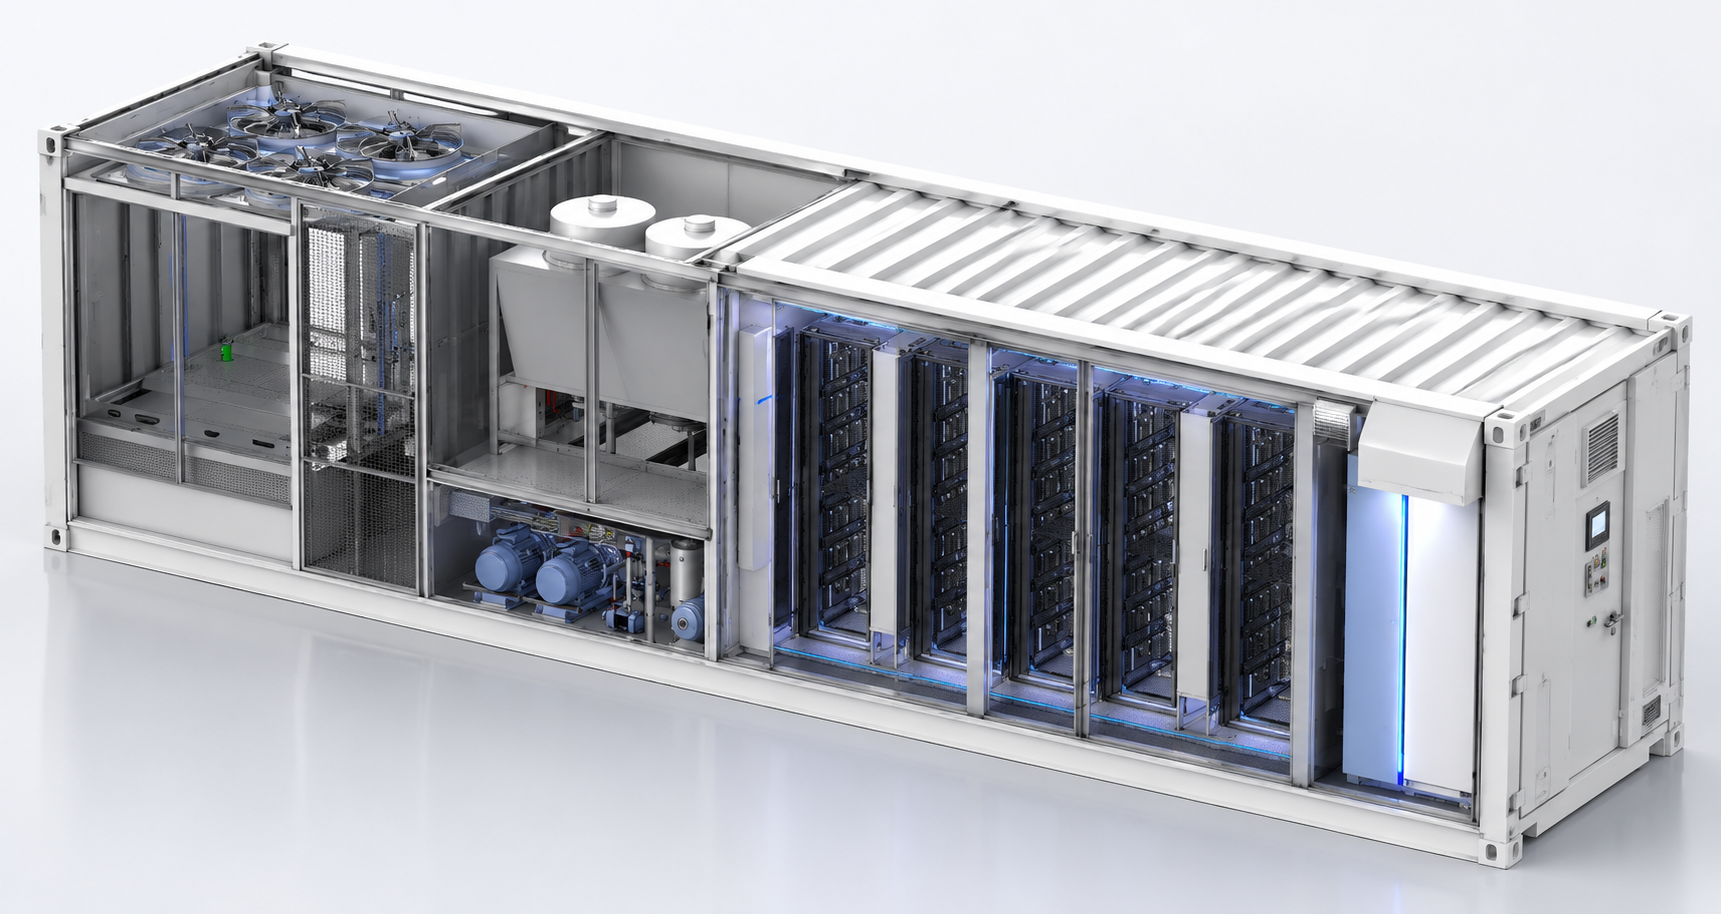
Dual-stack containerized data centers housing up to 9x 45U racks with quick-disconnect CDU manifolds.
Bare-metal instances, dedicated multi-GPU nodes, and isolated full-rack high-bandwidth clusters.
Engineering design, international customs & freight, power hookup, and 24/7 hardware telemetry.
Traditional data centers waste up to 40% of incoming power on cooling fans and air movement. PARICH direct-to-chip liquid cooling targets heat at the source, reducing PUE down to 1.16 and enabling 35kW+ per rack power density.
Engineered specifically for sustained large language model (LLM) training, multi-modal inference, and HPC workloads.
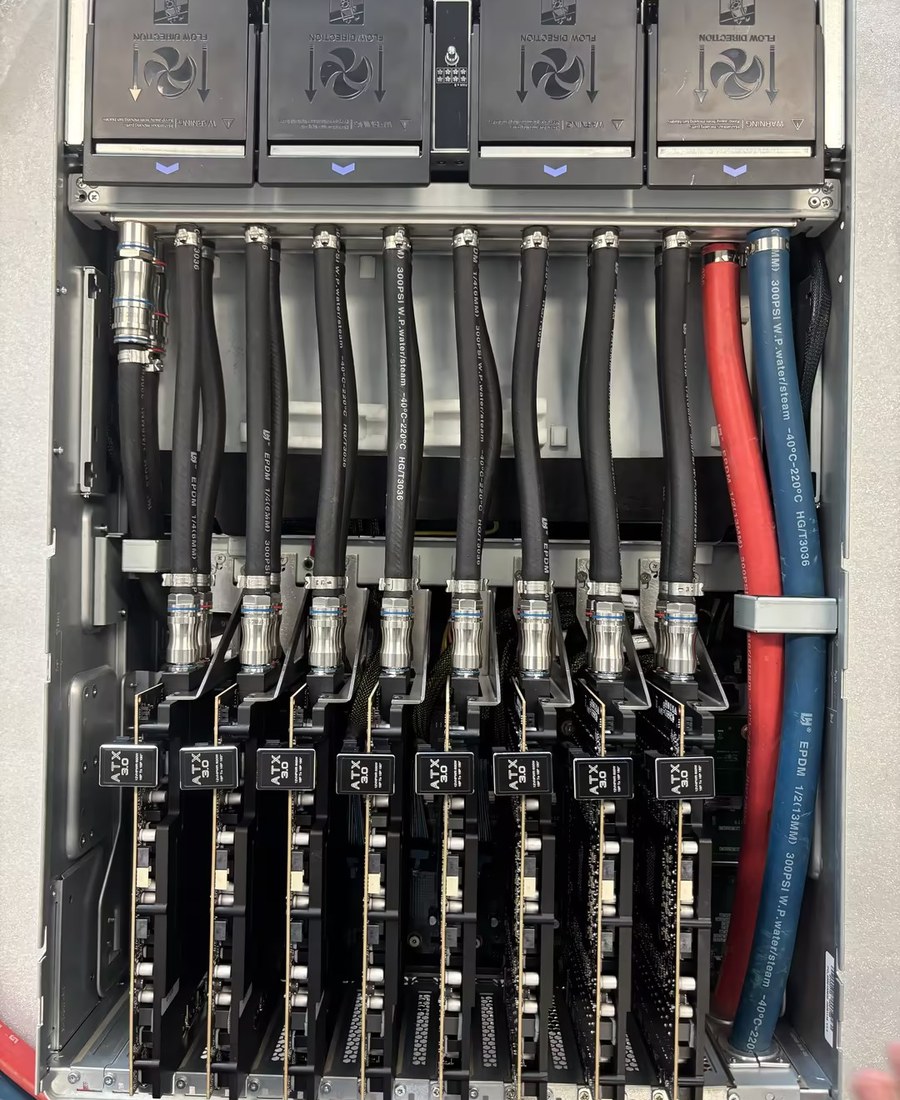
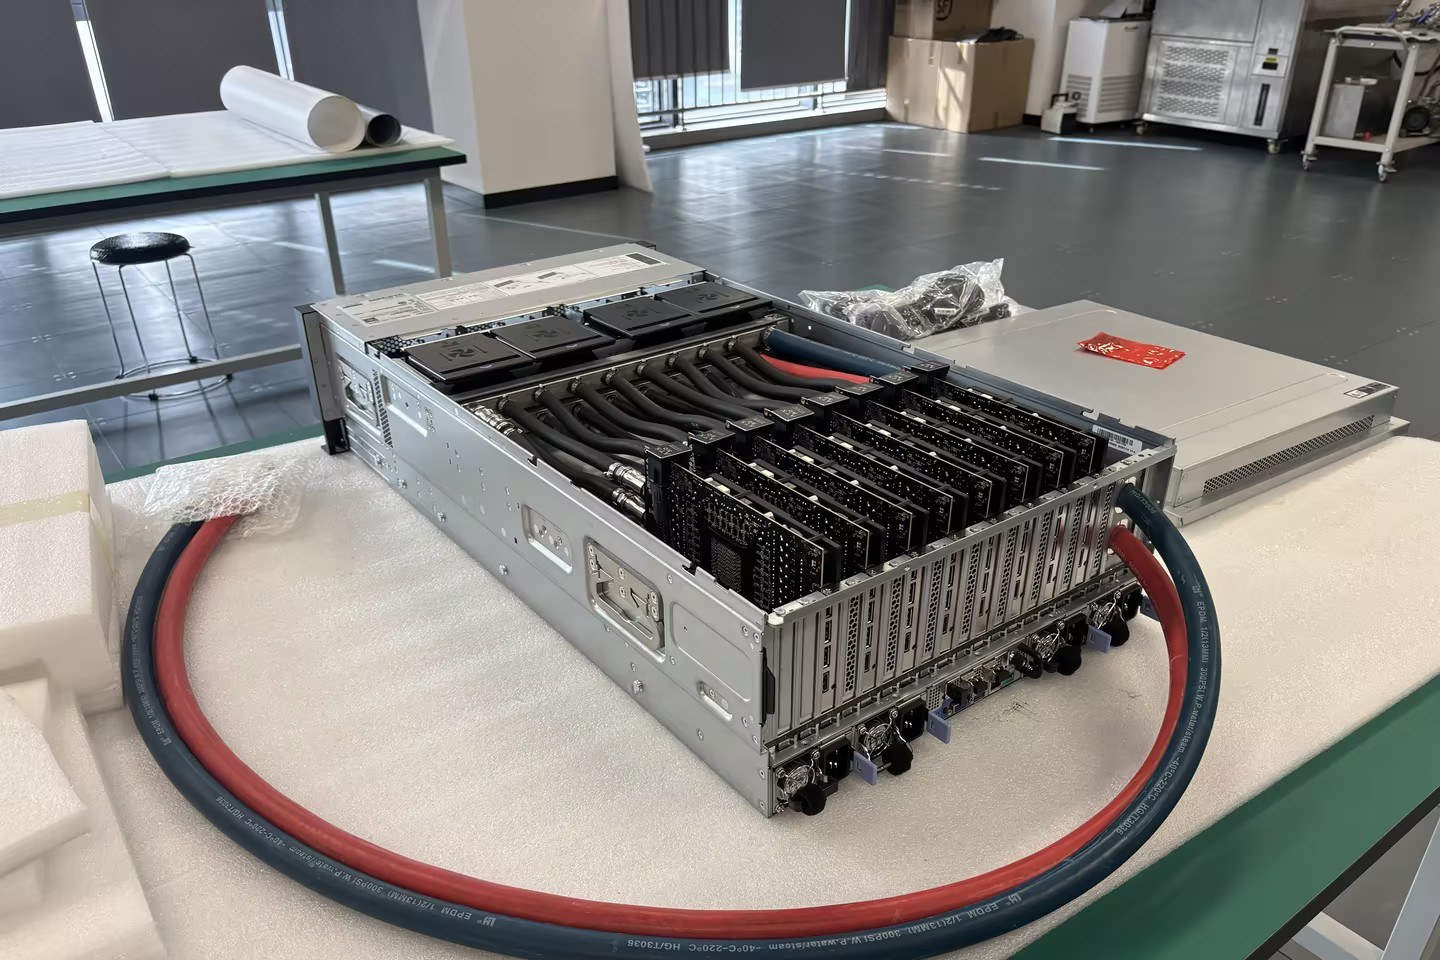
Designed for standard air-cooled data center facilities needing extreme GPU density without liquid piping infrastructure.
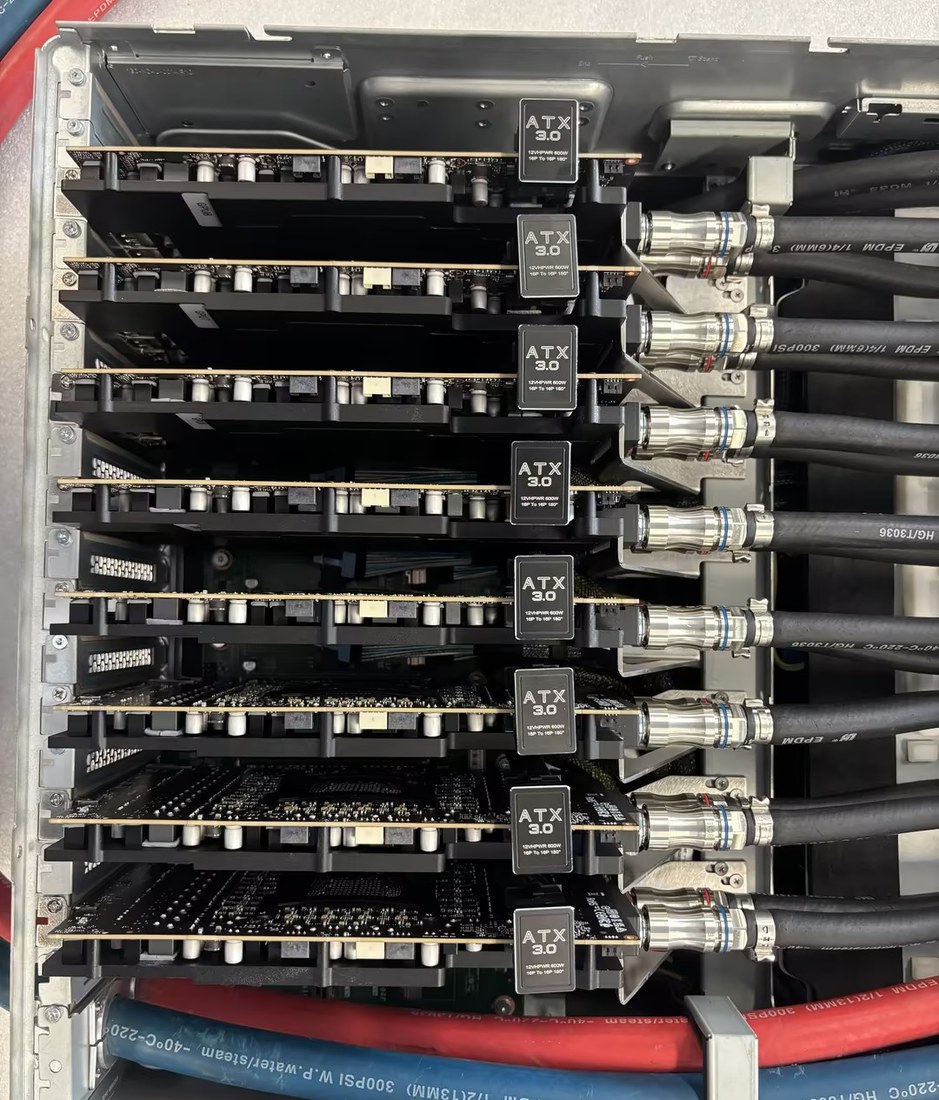
Custom-milled high-purity copper cold plates engineered for direct contact with GPU core dies and VRAM chips.
Deploy multi-megawatt compute clusters anywhere in weeks instead of years. Pre-tested, self-contained data center environments.
Features integrated CDU (Coolant Distribution Unit), 3-Phase 400V power distribution, automated fire suppression, emergency backup ventilation, and remote telemetry monitoring.
Whether you need on-demand GPU instances or dedicated container space for your own hardware, PARICH offers scalable access models.
Dedicated bare-metal instances featuring NVIDIA RTX 5090, PRO 6000, and B300 accelerators with root access and unthrottled NVLink/RoCE performance.
Lease full rack pods or entire PARICH container units. Bring your own server hardware into our pre-cooled, powered, and monitored facility infrastructure.
Custom-wired cluster topologies with ultra-low latency InfiniBand switches, dedicated high-speed NVMe flash arrays, and isolated network VLANs.
24/7/365 physical and digital support. On-site PARICH engineers handle rack-and-stack, cable routing, coolant topping, and rapid hardware replacement.
A seamless, engineering-led lifecycle from initial workload analysis to operational handoff.
Thermal assessment, target GPU count, power budget, and site constraints definition.
CDU piping schematics, PDU power balances, network fabric mapping & rack layouts.
Factory assembly, custom BIOS/firmware flashing, stress burn-in & leak testing.
International customs clearance, secure transport, and site delivery.
Power hookup, liquid loop purging, network isolation & cluster burn-in.
24/7 telemetry monitoring, preventative maintenance & hardware replacement SLA.
Real-world AI infrastructure projects delivered across primary Asia-Pacific and global regions.
Deployed custom liquid-cooled PARICH GI4205L servers integrated with 100G RoCE networking for real-time model inference and physics simulation.
Engineered isolated high-density rack pods with direct CDU liquid loops and custom power redundancy to satisfy strict latency and uptime requirements.
Managed turnkey international shipping, local customs, site installation, and network commissioning for a large-scale public compute cloud.
Delivered a factory-assembled dual-container DC pod to a high-ambient temperature region, maintaining sub-1.18 PUE under heavy continuous load.
Consult with PARICH systems engineers. We will analyze your GPU workload, thermal limits, and budget to provide a turnkey deployment proposal within 24 hours.